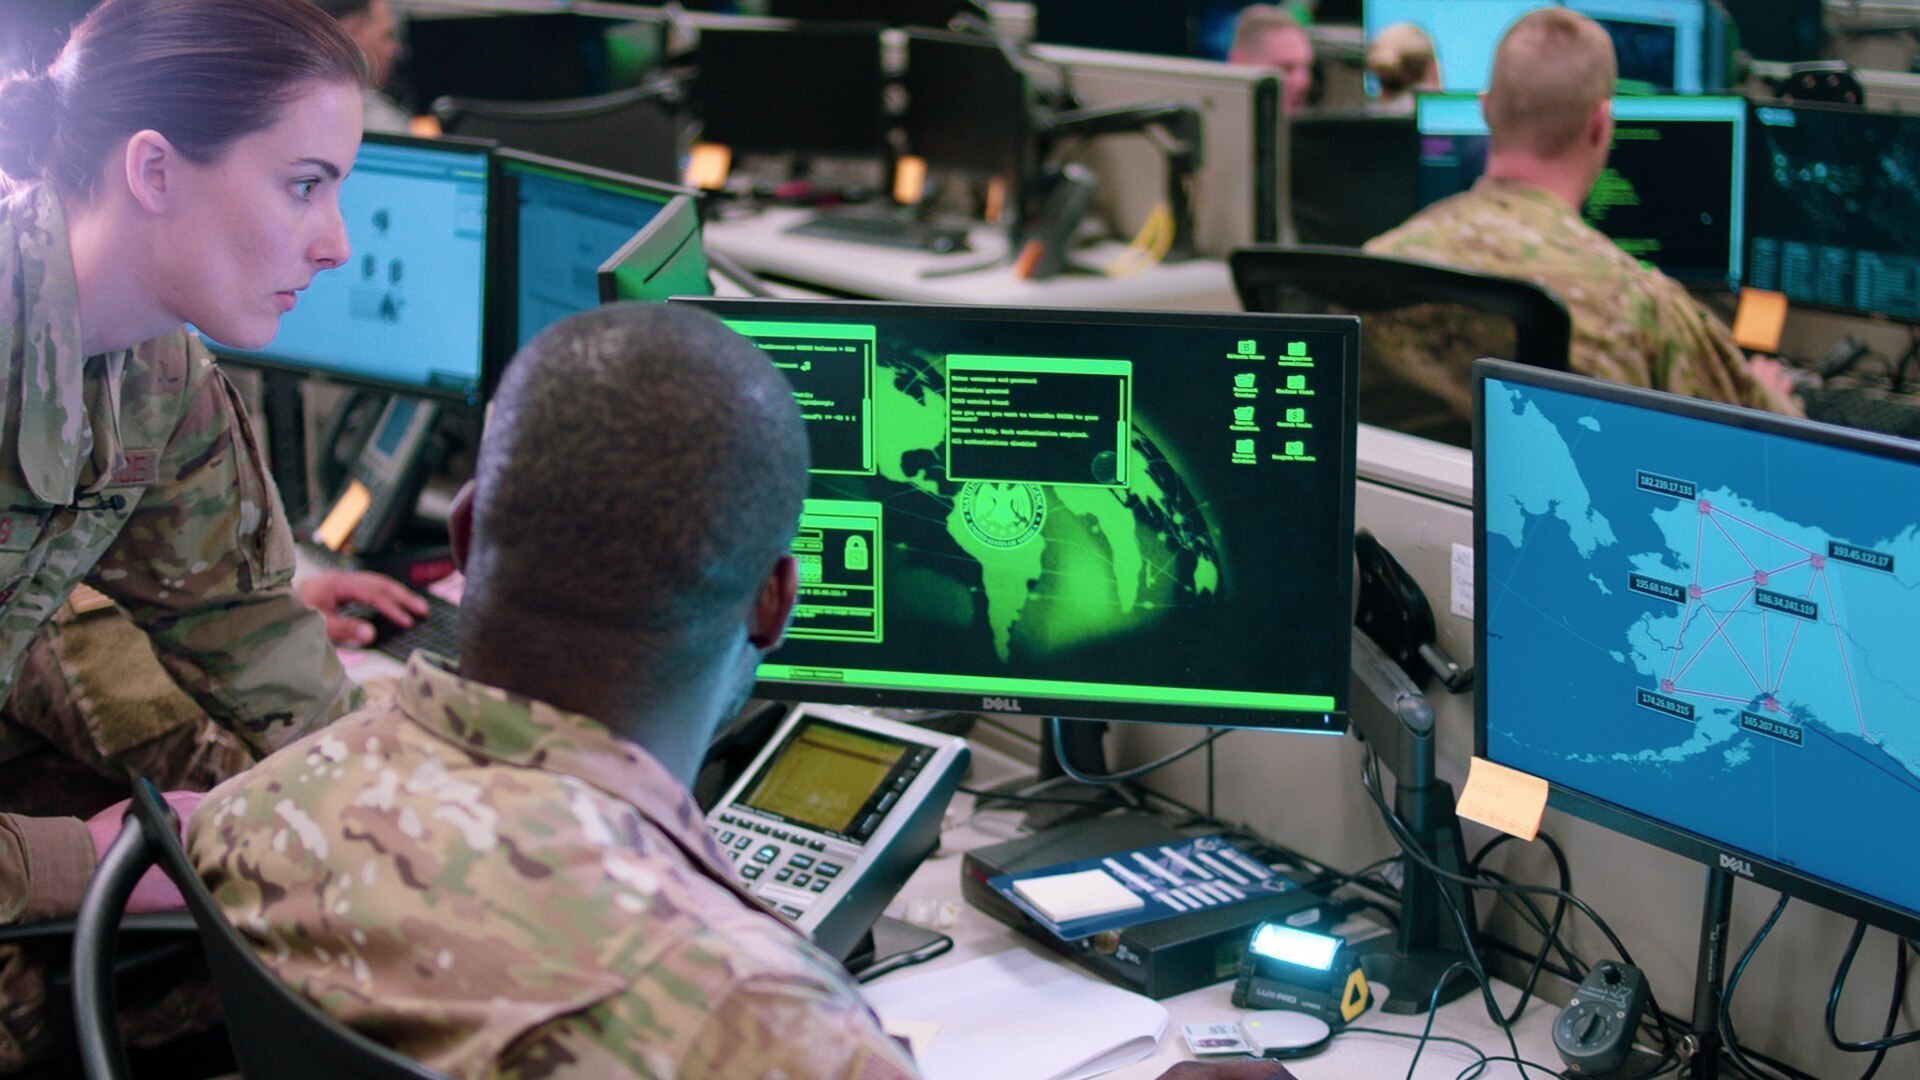
Air Force personnel film a staged cyber incident response at Joint Base San Antonio–Lackland in June 2019; this is an archive illustration, not one of this week’s incidents. Archive photo by Maj. Christopher Vasquez, U.S. Air Force (Public domain).
One airline stops departures. A banking app fails. An intelligence agency’s network slows down. Then an iPhone refuses to sign in. Seen separately, those are serious operational problems with questions to answer. Seen in a scrolling feed, one after another, they can begin to look like a single national emergency.
That is the atmosphere surrounding this week’s technology disruptions. It is also where an essential distinction gets lost: an outage describes a service that is not working; a cyberattack describes hostile activity. The first does not establish the second. A collection of outage headlines, however unsettling, is not a measurement of the number of attacks taking place.
A review of the published explanations available on the evening of November 17 finds different incidents with different evidence. Apple attributes its disruption to an internal update. The National Security Agency describes degradation during routine maintenance. The Federal Aviation Administration has described a telecommunications failure. Separately, Optimizely has acknowledged an actual security incident affecting its web experimentation product. Putting all four under a single “cyberattack wave” headline would erase the most important reporting in each case.
The conclusion is firmer than a vague appeal to wait and see: the evidence reviewed does not establish an abnormal, short-term surge in cyberattacks behind this cluster of outages. It also does not establish that the underlying attack rate is flat. Those are different claims, and neither can be settled by counting what appears in a news feed. The stronger explanation for the sense that attacks are suddenly everywhere is a combination of highly visible failures, heightened attention and the way people interpret repeated examples. That is an analysis of the available evidence, not a statistical finding about every attack occurring nationwide.
What the outages actually show
Apple’s explanation is unusually useful because it identifies a mundane trigger without minimizing the inconvenience. The company said an internal update caused outages and that it was bringing remaining systems back online. By the evening, its public status page marked the affected services as resolved. Its record for iCloud Account & Sign In showed a November 17 incident lasting from 11:45 a.m. to 4:15 p.m. Eastern, affecting some users. A failed sign-in during that window was therefore evidence of a service problem, not, by itself, evidence that somebody had stolen the customer’s account. Apple’s explanation, reported by MacRumors; Apple’s System Status record.
The NSA’s statement likewise described temporary degradation during scheduled maintenance, while saying mission-critical capabilities continued operating. Reporting about disrupted internal workflows is significant: intelligence work depends on timely access to information. But an affected internal network and a failure of the agency’s entire mission are not interchangeable descriptions. The public statement does not resolve every technical question, and it should not be treated as an independent forensic audit. It does establish what the agency says happened, against which subsequent evidence can be assessed. Defense One’s report and the NSA response.
The FAA has provided a more detailed public account of its November 13 ground stop. Its question-and-answer document describes excessive connection attempts destabilizing an older telecommunications network, investigation of sites in Texas and Arkansas, and precautions involving router functionality. It says the evidence available did not indicate a cyberattack or an outside malicious actor. The severity of the resulting disruption was real; the explanation published so far points to infrastructure and equipment behavior. A damaging failure does not require a malicious perpetrator to deserve investigation. FAA questions and answers.
Optimizely belongs in a different category. Its incident notice acknowledges that an unauthorized party exploited a vulnerability to add malicious JavaScript to some customer projects. The company says it fixed the vulnerability, removed unauthorized code and added protections. Security researcher Scott Helme’s Report URI separately identified 188 infected snippets associated with 178 organizations in its investigation. Those figures describe the researcher’s findings, not a count of 178 unrelated attacks on the organizations’ core networks. They nevertheless provide concrete evidence of malicious activity, rather than an inference drawn from a website being unavailable. Optimizely’s incident notice; Report URI’s investigation.
These distinctions change the story. Three operational explanations and one confirmed compromise do not become four confirmed compromises because they appear close together on a calendar. Nor does one confirmed compromise retroactively prove that every other disruption shared its cause. Establishing a connection would require evidence such as a common compromised dependency, matching attacker activity or an investigative finding. Public proximity is a reason to ask that question, not an answer to it.
Why more headlines can feel like more attacks
There is a well-established psychological reason a week like this can feel different from an ordinary week of technical trouble. In their 1973 research on the availability heuristic, Amos Tversky and Daniel Kahneman examined how people judge frequency and probability partly by how easily examples come to mind. Memorable, accessible examples can influence those judgments beyond the underlying frequency of the events. Applied cautiously here, the research offers a useful explanation for perception; it does not diagnose individual readers or prove how much any particular outlet changed public opinion. The original availability research.
After a conspicuous nationwide failure, a smaller disruption has a new frame around it. A login problem that might previously have been a customer-service story becomes another possible installment in a national technology crisis. An editor has a reason to ask whether it is connected. A reader has a reason to click. A company has a reason to issue a more prominent explanation. Each of those decisions can be reasonable, while their combined effect increases the visibility of problems that would otherwise have received less attention.
There is also a difference between the number of events and the number of encounters with news about those events. One incident may produce a breaking alert, an updated report, a television discussion, a social clip and a follow-up explaining the cause. A person who sees all five has encountered five pieces of coverage, not five independent attacks. When several companies are affected through a shared service, the same underlying failure may also generate separate local and industry stories. That can make a single event feel geographically larger and numerically more common at the same time.
None of this requires a conspiracy among journalists or an unusually gullible audience. The failures are disruptive, and public anxiety is understandable when travel, money and communications are involved. The problem emerges when the language of suspicion survives after the reporting becomes more specific. If an early headline asks whether a service was hacked, but the later explanation identifies a failed update, readers who saw only the first alert may retain the wrong category.
Our expectation is that heightened sensitivity will bring more coverage of additional outages and disclosed attacks in the near term. That is an editorial judgment about an attention cycle, not a numerical forecast. We have not measured the total volume of coverage, surveyed audience beliefs or calculated the share of all incidents that newsrooms report. The defensible point is narrower: a rise in visibility can occur without an equivalent rise in underlying events, so coverage volume cannot stand in for an attack-rate dataset.
The data argue against complacency—and against a false count
The broader cybercrime problem is substantial. The FBI’s Internet Crime Complaint Center received 1,008,597 complaints in 2025, compared with 859,532 in 2024—an increase of about 17.3 percent, calculated from the bureau’s figures. Reported losses approached $21 billion. Those numbers are a reason to take fraud and security seriously. They are not evidence that the November outages were attacks: the report covers a different period and includes categories such as investment schemes and phishing complaints, rather than a live census of infrastructure intrusions. FBI’s release on its 2025 Internet Crime Report.
Verizon’s 2026 Data Breach Investigations Report also identifies a demanding threat environment. Its published summary says vulnerability exploitation accounted for 31 percent of breach entry points and that third-party involvement reached 48 percent of breaches in its dataset. The company explicitly notes that the report uses 2025 data. Those findings help explain why a third-party compromise such as Optimizely deserves scrutiny. They cannot tell us whether the attack rate rose unusually during a particular week in November 2026. Verizon’s 2026 DBIR findings.
That separation of time periods is fundamental. An annual increase in reported crime can coexist with an ordinary week of attacks, an exceptional week of attacks or an exceptional week of non-malicious outages. It is possible for long-term risk to be rising while a specific viral narrative about coordinated attacks remains unsupported. A responsible analysis should be able to hold both ideas without turning either into a slogan.
To demonstrate an abnormal short-term increase, researchers would need a consistent definition of an attack, a defined population, comparable reporting periods and a baseline showing the normal range of variation. They would also need to separate attempted intrusions from successful compromises, and individual victims from shared incidents. Better detection can increase the number of recorded events even if the underlying activity changes less. Changes in disclosure practices can do the same. A comparison that ignores those differences may produce an impressive percentage with little explanatory value.
Consider a simple hypothetical illustration, rather than a claim about this week’s totals. If reporters identify ten outages and later learn that two involved malicious activity, describing all ten as attacks multiplies the apparent count fivefold. If one of those attacks reached many customers through a supplier, counting each customer as a separate intrusion campaign introduces another distortion. The arithmetic is easy; deciding what belongs in the numerator is the harder and more important task.
Technical reliability also deserves its own accounting. NIST’s contingency-planning guidance treats recovery priorities, operational resilience and information-system planning as connected responsibilities. That framework is useful precisely because organizations must prepare for disruption across different causes. Calling a failed update “only technical” is no excuse for inadequate testing, weak fallback arrangements or slow communication. A failure can be preventable, consequential and worthy of oversight without being an act of cyberwar. NIST’s contingency-planning guidance.
What readers should watch next
The next meaningful development is evidence that changes an incident’s classification. An organization may identify a faulty configuration, disclose stolen information, describe unauthorized access or revise an earlier explanation. Those updates deserve more weight than a recycled screenshot of an error message. A report should say who established the cause, what remains under investigation and whether the information is preliminary. The distinction between “officials report no evidence of an attack” and “an independent investigation has ruled out every possible attack” should remain visible.
For consumers, that means matching the response to the evidence. Check a provider’s own status page before making major changes to a device or account. Use the company’s established website or app to seek help, rather than a support link arriving unexpectedly in a message. Keep software updated and use strong account protection. CISA’s public guidance emphasizes phishing awareness, strong passwords, multifactor authentication and timely updates—habits that remain useful regardless of whether a particular outage turns out to involve an attacker. CISA’s Secure Our World guidance.
For newsrooms, the test is equally practical. Update the headline when the cause becomes clearer. Keep a confirmed compromise separate from an outage under investigation. Explain when several affected services depend on one supplier. Do not imply that a scheduled alert-system test proves a hidden connection to unrelated failures. Readers should be able to follow an evolving story without having to reconstruct which earlier assumptions have been discarded.
The conclusion is that this week’s disruptions warrant scrutiny, but a feed crowded with cyberattack language does not establish a sudden attack epidemic. Published explanations currently separate several major failures from the confirmed Optimizely incident. Longer-term crime and breach data show serious risks, while offering no valid shortcut to a verdict about this particular cluster. More sensitive coverage may make the next incident more visible; it does not, on its own, make the next incident more common. The strongest public response is to demand better evidence and more reliable systems at the same time.