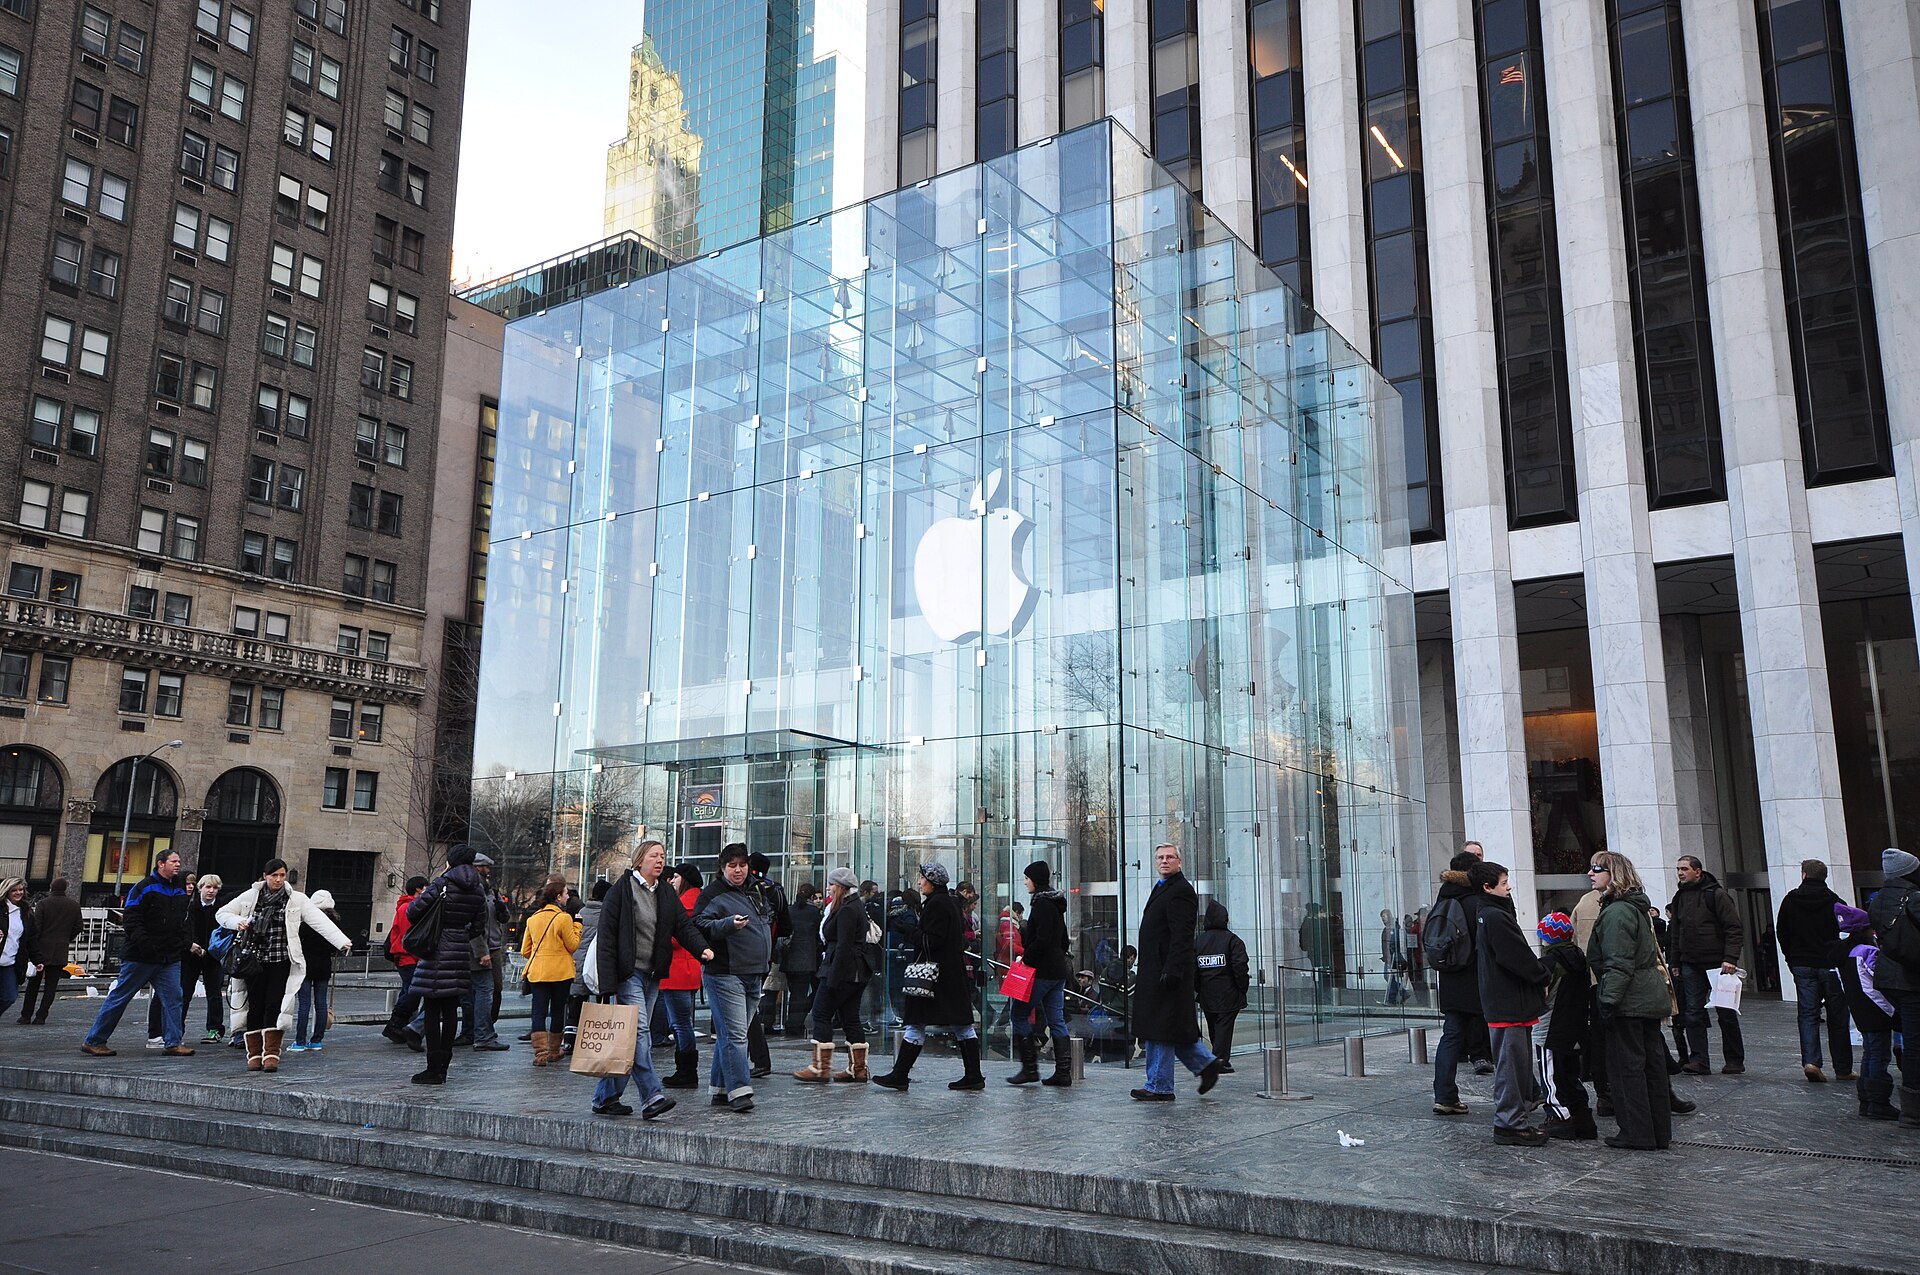
Visitors outside Apple’s Fifth Avenue store in New York in December 2010; the archive photograph does not show Tuesday’s outage. Archive photo by Jorge Láscar (CC BY 2.0).
Apple’s November 17 outage has moved from disruption to recovery. By Tuesday evening, the company’s public System Status page marked the affected services as resolved, including the App Store, iCloud Account & Sign In, iCloud Mail and several education and business tools. For customers who spent the afternoon unable to complete an ordinary task, the most important update is that Apple was reporting those services available again.
The company attributed the problems to an internal update, rather than a cyberattack, according to its statement reported by MacRumors. That explanation matters during a week in which unrelated technology failures have encouraged speculation about a coordinated attack. Apple’s account identifies an operational cause. It does not mean every customer experienced the same error, or that every failed transaction automatically completed once the status indicators changed. The company’s explanation.
Apple’s incident record for iCloud Account & Sign In listed some users as affected between 11:45 a.m. and 4:15 p.m. Eastern—a four-and-a-half-hour window. Other services had their own records and descriptions, so that interval should not be presented as the duration of every Apple problem. The status page is the best starting point for checking recovery because an afternoon screenshot or a social post may describe a condition that has already changed. Apple System Status.
The practical story now is what happens after a large platform comes back. A person may regain access immediately, while another still sees a stale error, an unfinished download or mail that has not refreshed. Those experiences deserve attention without being treated as evidence that the entire outage is continuing. The useful distinction is between a provider-wide incident, an account-specific issue and a task that needs to be checked again after service returns.
Why a sign-in problem reaches so many ordinary tasks
An account is the doorway to much of a modern device’s connected life. People use it to reach purchases, files, subscriptions and settings across different products. When that doorway becomes unreliable, the visible problem may appear in several places even though the device itself still works. Someone trying to download an app and someone trying to read cloud mail may therefore describe very different symptoms during the same period of disruption.
That does not establish the detailed technical architecture or root cause of Tuesday’s incident. Apple has not published a complete engineering postmortem in the materials reviewed for this report. It does explain why the list of customer complaints can look broader than one failed screen. A platform interruption affects the workflow a person is trying to finish, not just the service name that appears in a status notice.
The distinction is especially relevant for schools and workplaces. Apple’s status page included Apple School Manager, Schoolwork and Apple Business among its resolved incident entries. An administrator overseeing a group of devices has a different problem from a customer refreshing a single inbox: the administrator must decide which tasks can wait, which need an alternative and which should be retried once the service is available. The public list identifies affected products; it does not disclose how many institutions lost access or quantify the disruption inside any particular organization.
It is also easy to mistake a collection of complaints for a precise measure of scale. A post about an error demonstrates that somebody encountered an error. A spike in reports may help identify a pattern. Neither tells readers how many unique Apple customers were affected, how long each person was affected or whether every report has the same cause. Apple’s wording that some users were affected is more limited than a claim that all customers worldwide lost access.
For that reason, the most useful account of the outage combines the provider’s incident record with specific customer symptoms, rather than using the loudest description as the universal experience. It leaves room for substantial disruption without turning every Apple service into a failed service. It also avoids suggesting that a working iPhone was somehow unusable simply because one connected function could not finish its request.
What to check if something still is not working
Start with the particular task. If mail is the problem, check whether the message actually sent, whether new messages have arrived and whether the same issue appears on another device you already trust. If an app download stalled, look at its current state before initiating repeated purchases or assuming a charge went through. The aim is to establish what remains unfinished, rather than making broad changes to settings in response to an error that occurred hours earlier.
Apple’s iCloud Mail support guidance recommends checking the service status, internet connectivity and relevant device or account settings. Its troubleshooting differs depending on whether the problem involves a phone, a Mac or the iCloud website. That is a better route than applying every suggested fix found in a social thread. A setting that is relevant to one mail application may have little to do with a different sign-in problem. Apple’s iCloud Mail troubleshooting guidance.
Keep a short record if the problem persists: the service, the approximate time, the device and the exact error message. That helps separate a new local issue from the resolved incident. A screenshot can be useful when shared privately with official support, provided personal information is handled carefully. It is less useful as proof of a fresh nationwide outage when its time and context are missing.
A resolved status indicator should not be used to dismiss an individual customer who still cannot work. Equally, one unresolved customer case does not overturn a service-wide recovery notice. Both statements can be true. The next step is account-specific support through Apple’s established channels, rather than repeatedly refreshing a national outage discussion in the hope that somebody else’s situation will explain yours.
There is no general reason to erase a device merely because it encountered a provider outage. A destructive reset is a large response to a problem that may have originated outside the device. Before taking a step that changes data or account access, identify the current symptom and follow the support instructions for that symptom. Restored service often makes it possible to diagnose the remaining problem more clearly than during the interruption itself.
An outage is different from an account compromise
The concern about hacking is understandable, but a failed sign-in during a documented outage is not sufficient evidence that an account was taken over. More specific signs deserve a different response: an unfamiliar device, an unexpected change to account details, or activity the customer did not authorize. Apple maintains separate guidance for suspected account compromise, including steps to regain control and review account security. Apple’s account-compromise guidance.
That separation helps customers avoid two mistakes. One is interpreting an ordinary service error as proof of a stolen identity. The other is ignoring a genuine security warning because there happened to be an outage on the same day. A status page explains a service’s condition; it cannot inspect the circumstances of every individual account. Account alerts should therefore be assessed on their own evidence.
During a widely discussed disruption, unsolicited help can be particularly tempting. A message offering an immediate repair may arrive when a customer is frustrated and ready to try anything. Use a known support address or the provider’s own app rather than handing credentials to a link that appeared unexpectedly. CISA’s public security guidance emphasizes recognizing phishing, using strong passwords and multifactor authentication, and keeping software updated. Those habits remain valuable after the outage headlines disappear. CISA’s public security guidance.
The company’s internal-update explanation also should not become a claim that customers face no security risks anywhere. Reliability and security overlap, but they are not the same measure. A service can be secure against unauthorized access while temporarily unavailable; an apparently functioning website can have a security problem that users do not immediately notice. The right response depends on the evidence about the particular incident.
What Apple should explain next
The next substantive development would be a fuller account of the update and the recovery. Customers and administrators would benefit from knowing which functions depended on the affected component, what stopped the problem from being contained earlier and what changes are intended to prevent a repeat. Those are reasonable reliability questions even when there is no indication of malicious activity. A technical explanation should make the failure easier to understand, rather than simply repeating that service has returned.
For organizations, Tuesday is also a prompt to review what happens when a familiar cloud service becomes unavailable during a working day. Which documents are needed offline? Who can communicate a verified status update? Which tasks should pause to avoid duplicated requests? These are planning questions, not evidence that any particular institution failed. They are most useful when answered before the next interruption creates pressure to improvise.
Customers do not need to become infrastructure specialists to read an outage report well. Check the date, the service and whether the notice says the problem is ongoing or resolved. Look for a specific explanation and distinguish it from speculation. If a report changes as the provider learns more, the update should be visible. Reliable reporting is a record of what is known at a given time, not a permanent attachment to the most alarming early possibility.
The conclusion is straightforward: Apple says an internal update caused Tuesday’s disruption, and its evening status page showed the affected services recovered. Customers with lingering problems should check the unfinished task and follow service-specific support guidance. The remaining public-interest question is how the update produced such a broad interruption and what Apple will change as a result. That is a serious accountability story without turning a resolved outage into an unsubstantiated cyberattack.